Jude Max GPU for Deep Learning Review: A Blueprint for Parallel Computing Optimization
This review examines the Jude Max GPU for Deep Learning book, a guide focused on practical CUDA and parallel computing techniques to accelerate AI model training and career advancement.
 By Elvis Dicki
Updated October 21, 2026
For developers and data scientists frustrated by slow model training times, the bottleneck often lies not in the model architecture but in inefficient code that fails to leverage modern hardware. The Jude Max GPU for Deep Learning addresses this exact pain point. This book positions itself as a practical blueprint for mastering parallel computing and CUDA programming to build high-performance AI models, targeting those ready to move beyond single-threaded limitations and tackle larger datasets. In essence, it promises to transform a slow, frustrating workflow into a fast and fluid process by providing the tools to write efficient code that unlocks a system’s full hardware potential.
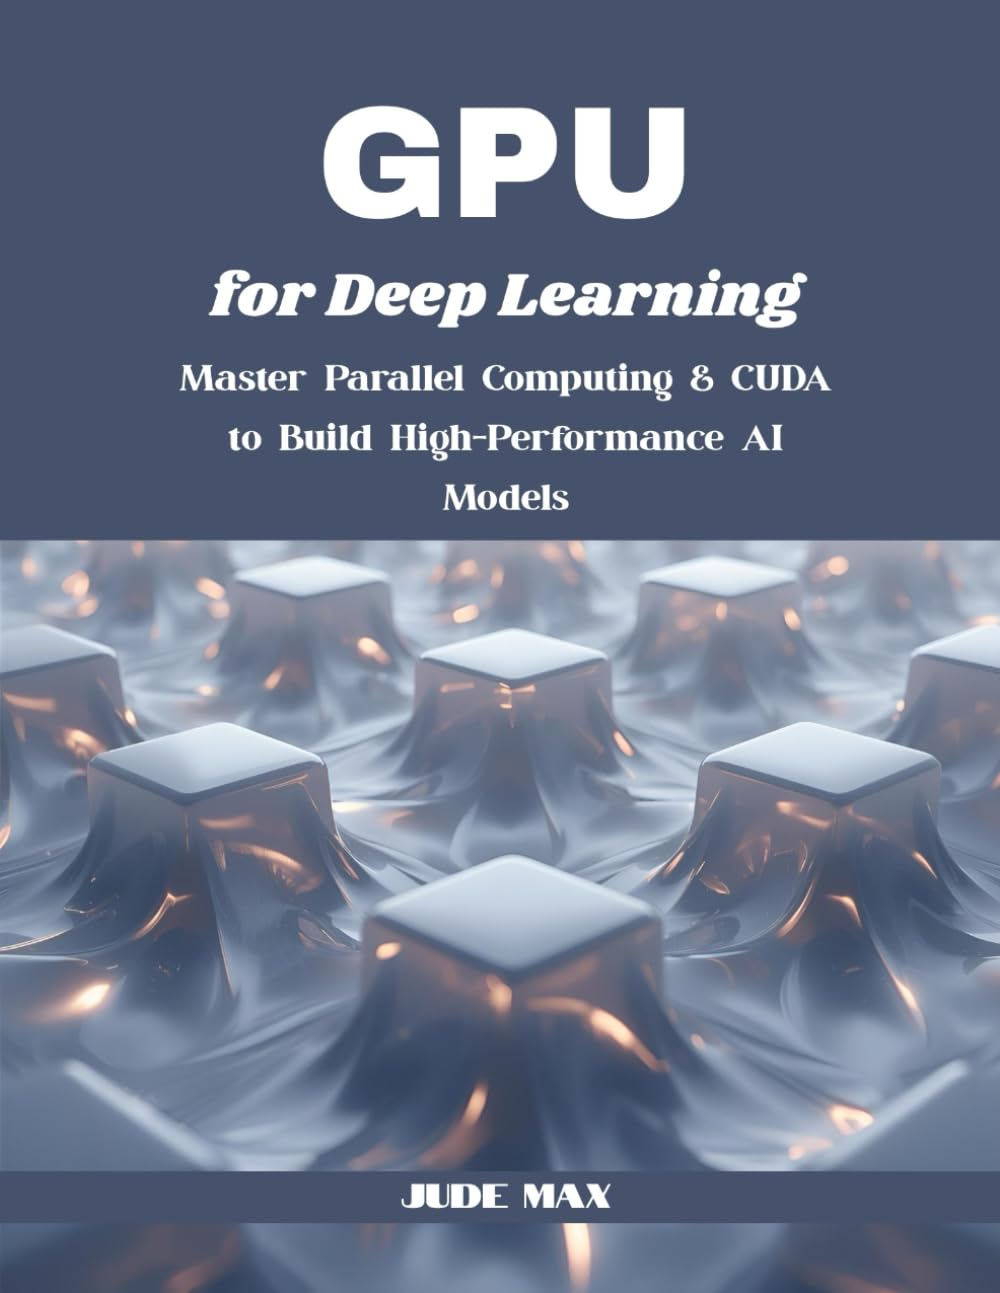
This review analyzes the specifications, stated features, and editorial insights for the Jude Max GPU for Deep Learning book. As a resource categorized under Neural Networks and Parallel Computer Programming, it aims to cover the complete stack from low-level CUDA kernels to high-level frameworks like PyTorch and TensorFlow. The bottom line: this is a career-focused technical guide designed for developers seeking concrete optimization skills rather than abstract theory.
Prime GPU for Deep Learning: Master CUDA Parallel
As an Amazon Associate we earn from qualifying purchases. Product prices and availability are accurate as of the date/time indicated.
Jude Max GPU for Deep Learning at a Glance
| Specification | Detail |
|---|---|
| Product Type | Book |
| Full Title | GPU for Deep Learning: Master Parallel Computing & CUDA to Build High-Performance AI Models |
| Author/Brand | Jude Max |
| Print Length | 89 pages |
| Publication Date | September 3, 2025 |
| Publisher | Independently published |
| Language | English |
| ISBN-13 | 979-8263670733 |
| Item Weight | 10.2 ounces |
| Dimensions | 8.5 x 0.21 x 11 inches |
Design and Build
As a physical book, the design and build pertain to its format and dimensions. The publication is listed as an independently published paperback with a print length of 89 pages. Its dimensions are 8.5 by 11 inches, a standard size that often accommodates technical diagrams and code snippets, with a thickness of 0.21 inches indicating a relatively slim volume. The item weight is specified as 10.2 ounces. The physical construction is typical for a trade paperback, though specific details about paper quality or binding durability are not listed by the manufacturer.
Performance and Features
Core Technical Coverage
The book’s stated performance is measured by the depth and utility of its technical content. It promises a complete stack approach, guiding readers from writing low-level CUDA kernels to integrating with high-level frameworks such as PyTorch and TensorFlow. This vertical integration is a key selling point, aiming to bridge the gap between hardware-level programming and popular AI development tools. The content is framed around solving real-world speed bottlenecks in deep learning workflows.
Optimization Techniques
A major focus is on performance optimization. The book covers expert techniques intended to accelerate AI model training, including memory coalescing, managing thread divergence, and implementing mixed-precision training methods. These are practical code optimizations targeted at yielding real-world speed gains for neural network training, directly addressing the common pain point of agonizingly slow training processes.
Scalability and Career Development
Beyond single-GPU optimization, the book delves into scaling ambitions. It includes guidance on implementing multi-GPU and distributed training setups to handle larger and more complex models and datasets. Uniquely, it pairs this technical instruction with a career blueprint, offering strategies for building a portfolio, preparing for technical interviews, and securing high-value roles in the AI field. This combination of hard technical skills and soft career guidance is a noted feature.
Setup, Support and Ownership
Setup for this product involves acquiring the physical book. As a published guide, there are no drivers, software installations, or hardware configurations required from the user’s side to begin reading. Regarding support, the book is independently published, and specific details about author support, official forums, or update channels for future editions are not listed. Ownership is straightforward; it is a one-time purchase of an educational resource. The publication date is in the future, which may relate to its current availability status. Readers interested in related hardware setups for AI work can explore resources on the best computer server for AI research and development.
What Owners Say
At the time of this analysis, there are no buyer review excerpts available for this product. The rating distribution shows no ratings across any star category. Therefore, there is no user-generated feedback to assess real-world results, practical application ease, or the effectiveness of the career advice offered within the book. Prospective buyers must rely solely on the publisher’s description and editorial summary for insights into the content’s value.
Pros and Cons
Pros
- Practical application focus over abstract theory.
- Covers the complete technical stack from CUDA to PyTorch/TensorFlow.
- Addresses specific optimization pain points like thread divergence.
- Includes scaling guidance for multi-GPU and distributed training.
- Integrates career development strategies with technical skills.
- Targets a clear need for faster deep learning code.
Cons
- Short 89-page length may limit depth on advanced topics.
- No customer reviews available to verify content quality.
- Future publication date may affect immediate availability.
- Independently published, with unclear support structure.
- Lacks user-validated benchmarks or results.
- Physical format only; digital version details not specified.
Who Should Buy It (and Who Should Skip It)
The Jude Max GPU for Deep Learning book is ideally suited for developers and data scientists who have foundational deep learning experience but are hindered by slow training times. It is for those ready to dive into parallel computing and GPU optimization with CUDA, seeking a practical guide that connects low-level code with popular frameworks. It also holds value for professionals aiming to advance their AI careers, as it explicitly covers portfolio building and interview preparation. For broader context on AI tools, readers might also be interested in expert picks for AI and software.
This book is likely not the best fit for complete beginners to deep learning, as it assumes existing model-building experience. Those seeking an in-depth, thousand-page reference tome on GPU architecture or theoretical parallel computing may find the 89-page length insufficient. Similarly, individuals looking for peer-validated learning resources or who prefer video tutorials and interactive courses should consider the lack of reviews and the static book format. If your primary interest is in pre-configured AI hardware rather than code optimization, resources reviewing the best high-performance computer server for AI applications may be more relevant.
Final Verdict
The Jude Max GPU for Deep Learning book presents a focused proposition: a practical guide to overcoming single-threaded bottlenecks in AI training through parallel computing and CUDA mastery. Its strengths lie in its stated complete-stack approach, covering everything from kernel-level optimizations to framework integration, and its unique inclusion of career advancement advice. The editorial summary highlights its potential to deliver immediate workflow improvements by addressing common inefficiencies like memory access patterns and thread divergence.
However, the evaluation comes with significant caveats due to the absence of user feedback and the relatively concise page count. The future publication date and independent publishing status add elements of uncertainty regarding availability and support. As an analytical review based solely on provided specifications and descriptions, this product appears to fill a specific niche for the hands-on developer ready to optimize. Prospective buyers must weigh the promise of a practical, career-focused blueprint against the lack of verifiable user experiences and the potential depth limitations of a shorter book. For related educational resources in tech, the cybersecurity books for beginners list offers a point of comparison.
FAQs
What prior knowledge is required for this book?
The book is targeted at individuals who have already built deep learning models but are facing slow training times. It assumes you are ready to move beyond a single-threaded approach. Therefore, a foundational understanding of neural networks and experience with a framework like PyTorch or TensorFlow is likely necessary to benefit from the optimization techniques discussed. It is not positioned as an introductory text to AI itself.
Does this book teach CUDA programming from scratch?
Based on the description, the book covers low-level CUDA kernels as part of its “complete stack” approach. It presents itself as a blueprint for mastering parallel computing and CUDA specifically for deep learning applications. While it may introduce CUDA concepts, its primary focus is on the practical application of these techniques to accelerate AI model training, rather than being a comprehensive, general-purpose CUDA programming textbook.
Are code examples provided in specific languages?
The product description mentions integration with high-level frameworks like PyTorch and TensorFlow, which use Python predominantly. It also discusses writing CUDA kernels, which typically use C/C++. While the exact language breakdown is not specified, it is reasonable to expect examples involving Python for framework code and C/C++ for CUDA kernel examples. The book’s practical focus suggests it includes actionable code snippets.
How does this book address multi-GPU setups?
One of the key selling points is teaching readers how to scale their training efficiently. The book includes guidance on implementing multi-GPU and distributed training setups. This is aimed at enabling users to tackle larger datasets and more complex models that cannot be efficiently processed on a single GPU, moving from individual optimization to system-level scaling strategies.
About the author

Elvis Dicki writes reviews and buying guides for CyberSecLabs.